

Winning over the long run starts with clean numbers, not gut feelings. If you want to know whether your sports model has found a useful betting opportunity, you need to compare its probability with a fair market estimate. That means converting sportsbook odds into implied probabilities, removing the bookmaker’s margin, and checking whether your model sees a meaningful difference. Here’s how to do it, how to calculate expected value, and how to keep your staking decisions sensible instead of chasing every small edge.
Table of Contents
Why Model Probability and No-Vig Odds Matter
Model probability is your estimate of how likely an outcome is to happen. For example, your model might give Team A a 56% chance of winning. Market-implied probability comes from the odds offered by a sportsbook. The catch is that those posted odds usually include a margin called the vigorish, or vig. That margin means the implied probabilities across all outcomes generally add up to more than 100%.
Removing the vig gives you a cleaner market benchmark. You can then compare your model’s estimate with the market’s no-vig probability instead of treating a bookmaker’s margin as if it reflects the likelihood of the outcome itself. The difference is called the edge: your model probability minus the no-vig market probability.
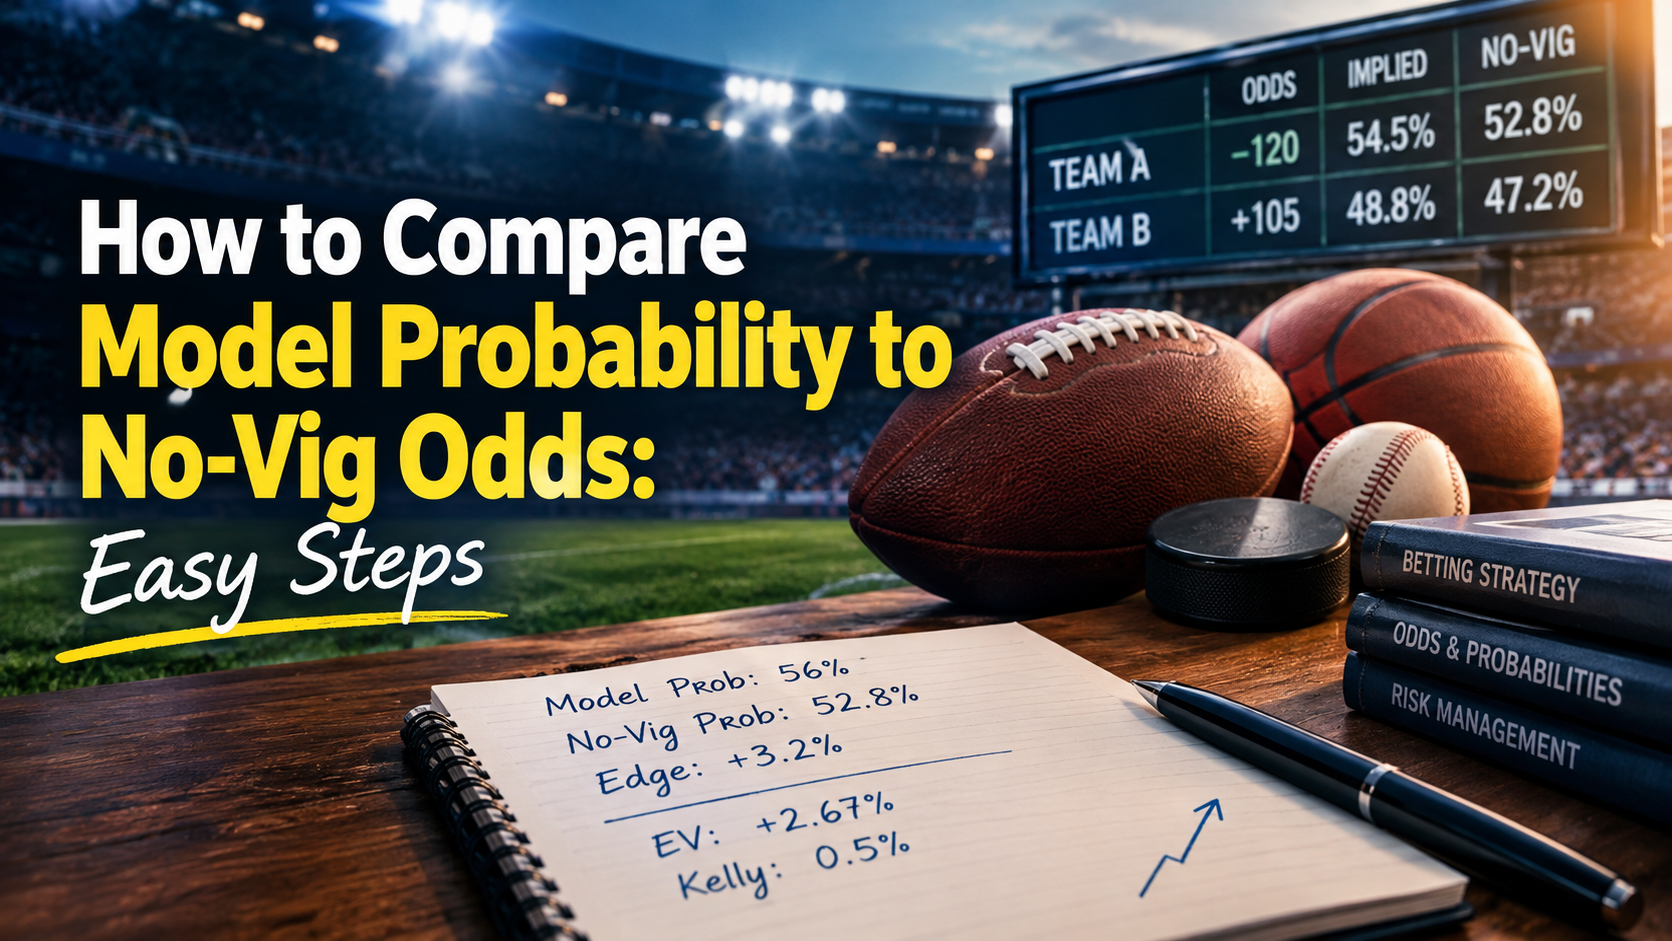
That difference is useful, but it is not a guarantee. A 56% model estimate against a 52.8% no-vig probability gives an edge of 3.2 percentage points. Whether it is worth acting on depends on the available price, model reliability, and uncertainty.
Convert Odds and Remove the Vig
For American odds, the implied probability formula depends on whether the odds are positive or negative. For positive odds of +A, calculate 100 divided by A plus 100. For negative odds of −A, use A divided by A plus 100, treating A as a positive number. So +150 implies 100 / 250, or 40%. Odds of −130 imply 130 / 230, or about 56.52%.
Decimal odds are more direct. Divide 1 by the decimal price. Odds of 2.50 imply a probability of 40%, while odds of 1.80 imply about 55.56%. Keep your odds format consistent throughout your calculations, and avoid rounding intermediate values too early.
Next, calculate the overround, which is the total of the raw implied probabilities minus 1. Imagine a two-outcome market where Team A is −120 and Team B is +105. Team A’s raw implied probability is about 54.55%, while Team B’s is about 48.78%. Together they total 103.33%, meaning the overround is roughly 3.33%.
A simple way to remove the margin is proportional normalization. Divide each outcome’s raw implied probability by the sum of the raw probabilities for all outcomes. In this example, Team A’s no-vig probability is about 52.79%, and Team B’s is about 47.21%. The two now add up to 100%.
The same method works for markets with three or more outcomes: divide each raw probability by their total. Confirm that the no-vig probabilities add up to approximately 1. This is a practical benchmark, not proof that market probabilities are perfectly accurate.
Check Your Model Before Comparing Probabilities
The comparison only means something if your model produces useful probabilities. A model can rank teams correctly but still misstate the actual chances. Calibration checks whether outcomes assigned similar probabilities happen at roughly the rates predicted over a large sample.
Two useful measures are the Brier score and log loss. The Brier score averages the squared difference between a predicted probability and the actual outcome, where the outcome is 1 for a win and 0 otherwise. Lower scores are better. Log loss penalizes confident predictions that turn out wrong more heavily.
If your model regularly calls outcomes 60% likely but those outcomes happen only around 53% of the time, you may be overstating your chances. Calibration methods such as Platt scaling or isotonic regression can help. Fit calibration on validation data, not training predictions.
Test the model on a timeline that prevents future injury information, confirmed lineups, closing odds, or postgame stats from leaking into earlier predictions. If an edge is smaller than the model’s uncertainty, it may just be noise.
A Step-by-Step Comparison Workflow
Start by recording the available odds with a timestamp, sportsbook, event, market, selection, and exact line. The line matters as much as the team or player. Over 47.5 is not the same market as Over 48.5, and a moneyline model that includes overtime should not be compared with a regulation-only market.
Convert each selection’s odds into raw implied probability, then calculate the overround for the complete market. Normalize the probabilities to remove the vig and check that the no-vig values add up to 1. Keep several decimal places during calculations to avoid rounding errors.
Now match the market data to the model output. Confirm that the event, selection, settlement rules, player, statistic, and line all agree. Player props need extra care because similar labels can describe different stats or conditions. If a feed changes an event or selection identifier, a bad match can make a perfectly ordinary price look like a huge edge.
Once the markets line up, compare the probabilities. Suppose Team A is −120 and Team B is +105. Team A’s no-vig probability is about 52.79%. If your model estimates 56%, the edge is about 3.21 percentage points.
That is a reason to investigate, not an automatic instruction to bet. Check price availability, calibration, and whether the edge can survive normal movement and uncertainty. Some workflows use minimum thresholds around 2% to 3% for major markets and higher for noisier props, but no threshold guarantees profit.
Calculate Edge, Expected Value, and Stake Size
Edge and expected value are related, but they answer different questions. Edge compares your model’s probability with the market’s no-vig probability. Expected value uses the actual price you can bet to estimate the average profit or loss per unit staked over many similar bets.
For decimal odds D and model probability p, the expected value per $1 is:
EV = p × (D − 1) − (1 − p)
Use the offered price, not a hypothetical fair price. If your model assigns a 56% chance and the available decimal odds are 1.8333, the estimated EV is about 0.0267 per $1 staked, or a 2.67% expected return before any additional costs. That is an estimate over repeated bets, not a promise about the result of one wager.
The best available price can change the decision. If the line moves before you place the bet, expected value can shrink or disappear. Include commissions or other costs where they apply, and confirm the price is still available.
For stake sizing, the Kelly criterion estimates a bankroll fraction for long-run growth. With decimal odds D, let b = D − 1, p be your model probability, and q = 1 − p. The full Kelly fraction is:
f = (b × p − q) / b*
Since probabilities are uncertain, some bettors use one-quarter or one-half Kelly instead. Apply stake caps and account for correlated bets tied to the same game or player.
Common Mistakes and Quality Checks
One of the easiest mistakes is forgetting to remove the vig. Comparing a model directly with raw implied probabilities can make an opportunity look worse or better than it really is. Another is comparing different markets or lines, such as a regulation-only model against a moneyline that includes overtime. Always verify the exact outcome and settlement rules before calculating an edge.
Stale prices and delayed data can also create false signals. If one side of a market updates while the other remains old, the no-vig calculation may be misleading. Feeds can list the same operator more than once, so deduplicate records before building a market consensus. Check that probabilities stay between 0 and 1 and sum to 1 after normalization.
Record the model probability, raw and no-vig probabilities, available price, edge, EV, stake, timestamp, and closing price. Closing line value (CLV) shows whether your price beat the closing benchmark. Positive CLV over a meaningful sample can signal good price selection, but it does not guarantee profit.
Review performance by sport, market, and sportsbook. If calibration worsens or edges stop holding up, investigate data quality, injuries, team style, market conditions, or the model. A short run of wins is not a reason to raise stakes; long-term evaluation needs enough observations to separate signal from variance.
How ATSwins Fits Into the Process
ATSwins provides AI-driven sports projections, fair lines, player prop projections, and betting splits across NFL, NBA, MLB, NHL, and NCAA. You can use its projections as a starting point for your model probability or as a comparison point for an in-house forecast. Its fair lines can also help you sanity-check your own calculations, while betting splits add context about market activity. Splits alone do not prove that a side is valuable, so treat them as supporting information rather than a prediction.
Use the tools consistently: compare the same market and line, record the timestamp, calculate the no-vig benchmark, and measure the difference against the model. Review EV, stake size, and CLV over time rather than judging a process by a handful of results. ATSwins has free and paid plans for different workflows.
Quick Reference Formulas
American +A: implied probability = 100 / (A + 100). American −A: A / (A + 100). Decimal odds D: 1 / D. Overround = sum of raw implied probabilities − 1. No-vig probability = raw probability / sum of raw probabilities.
Edge equals model probability minus no-vig market probability. Expected value per $1 at decimal odds D equals p × (D − 1) − (1 − p). Full Kelly = (b × p − q) / b, where b = D − 1 and q = 1 − p. Fractional Kelly multiplies this by a scaling factor, subject to a stake cap.
Conclusion
Comparing model probability with no-vig odds gives you a clearer way to judge whether a price may offer value. Convert the odds, remove the margin, match the exact market, and compare the fair market probability with a calibrated model estimate. Then calculate EV using the real price and keep stake sizes conservative. Tracking decisions and CLV helps evaluate the process over time. ATSwins can support that process with sports projections, fair lines, player prop projections, and betting splits, but disciplined checks and realistic expectations still matter.
Frequently Asked Questions
What does it mean to compare model probability to no-vig odds?
It means comparing your model’s estimate of an outcome with the market’s implied probability after removing the sportsbook’s margin. The difference is the estimated edge. A positive edge suggests an opportunity, not a guaranteed win.
How do I compare model probability to no-vig odds?
Convert each offered price into implied probability, add the probabilities together to find the overround, and divide each raw probability by that total. Then subtract the no-vig probability from your model probability. Confirm that the market, line, and settlement rules match before interpreting the result.
Why are no-vig odds better for this comparison?
Posted odds include a margin, so their raw implied probabilities usually add up to more than 100%. Removing that margin creates a more consistent market benchmark. It makes the comparison more useful, though it is not a perfect true probability.
How can ATSwins help?
ATSwins offers AI-powered projections, fair lines, player prop projections, and betting splits across major sports. You can use these as a reference when checking your own probabilities and reviewing market context. Verify the exact line and price, and treat projections as estimates.
What mistakes should I avoid?
Don’t forget to remove the vig, compare mismatched markets, ignore calibration, or treat a tiny edge as certain profit. Stale odds and incorrect player or event mappings can also distort the result. Keep detailed records of prices, probabilities, stakes, and closing lines so you can review performance with a larger sample.