

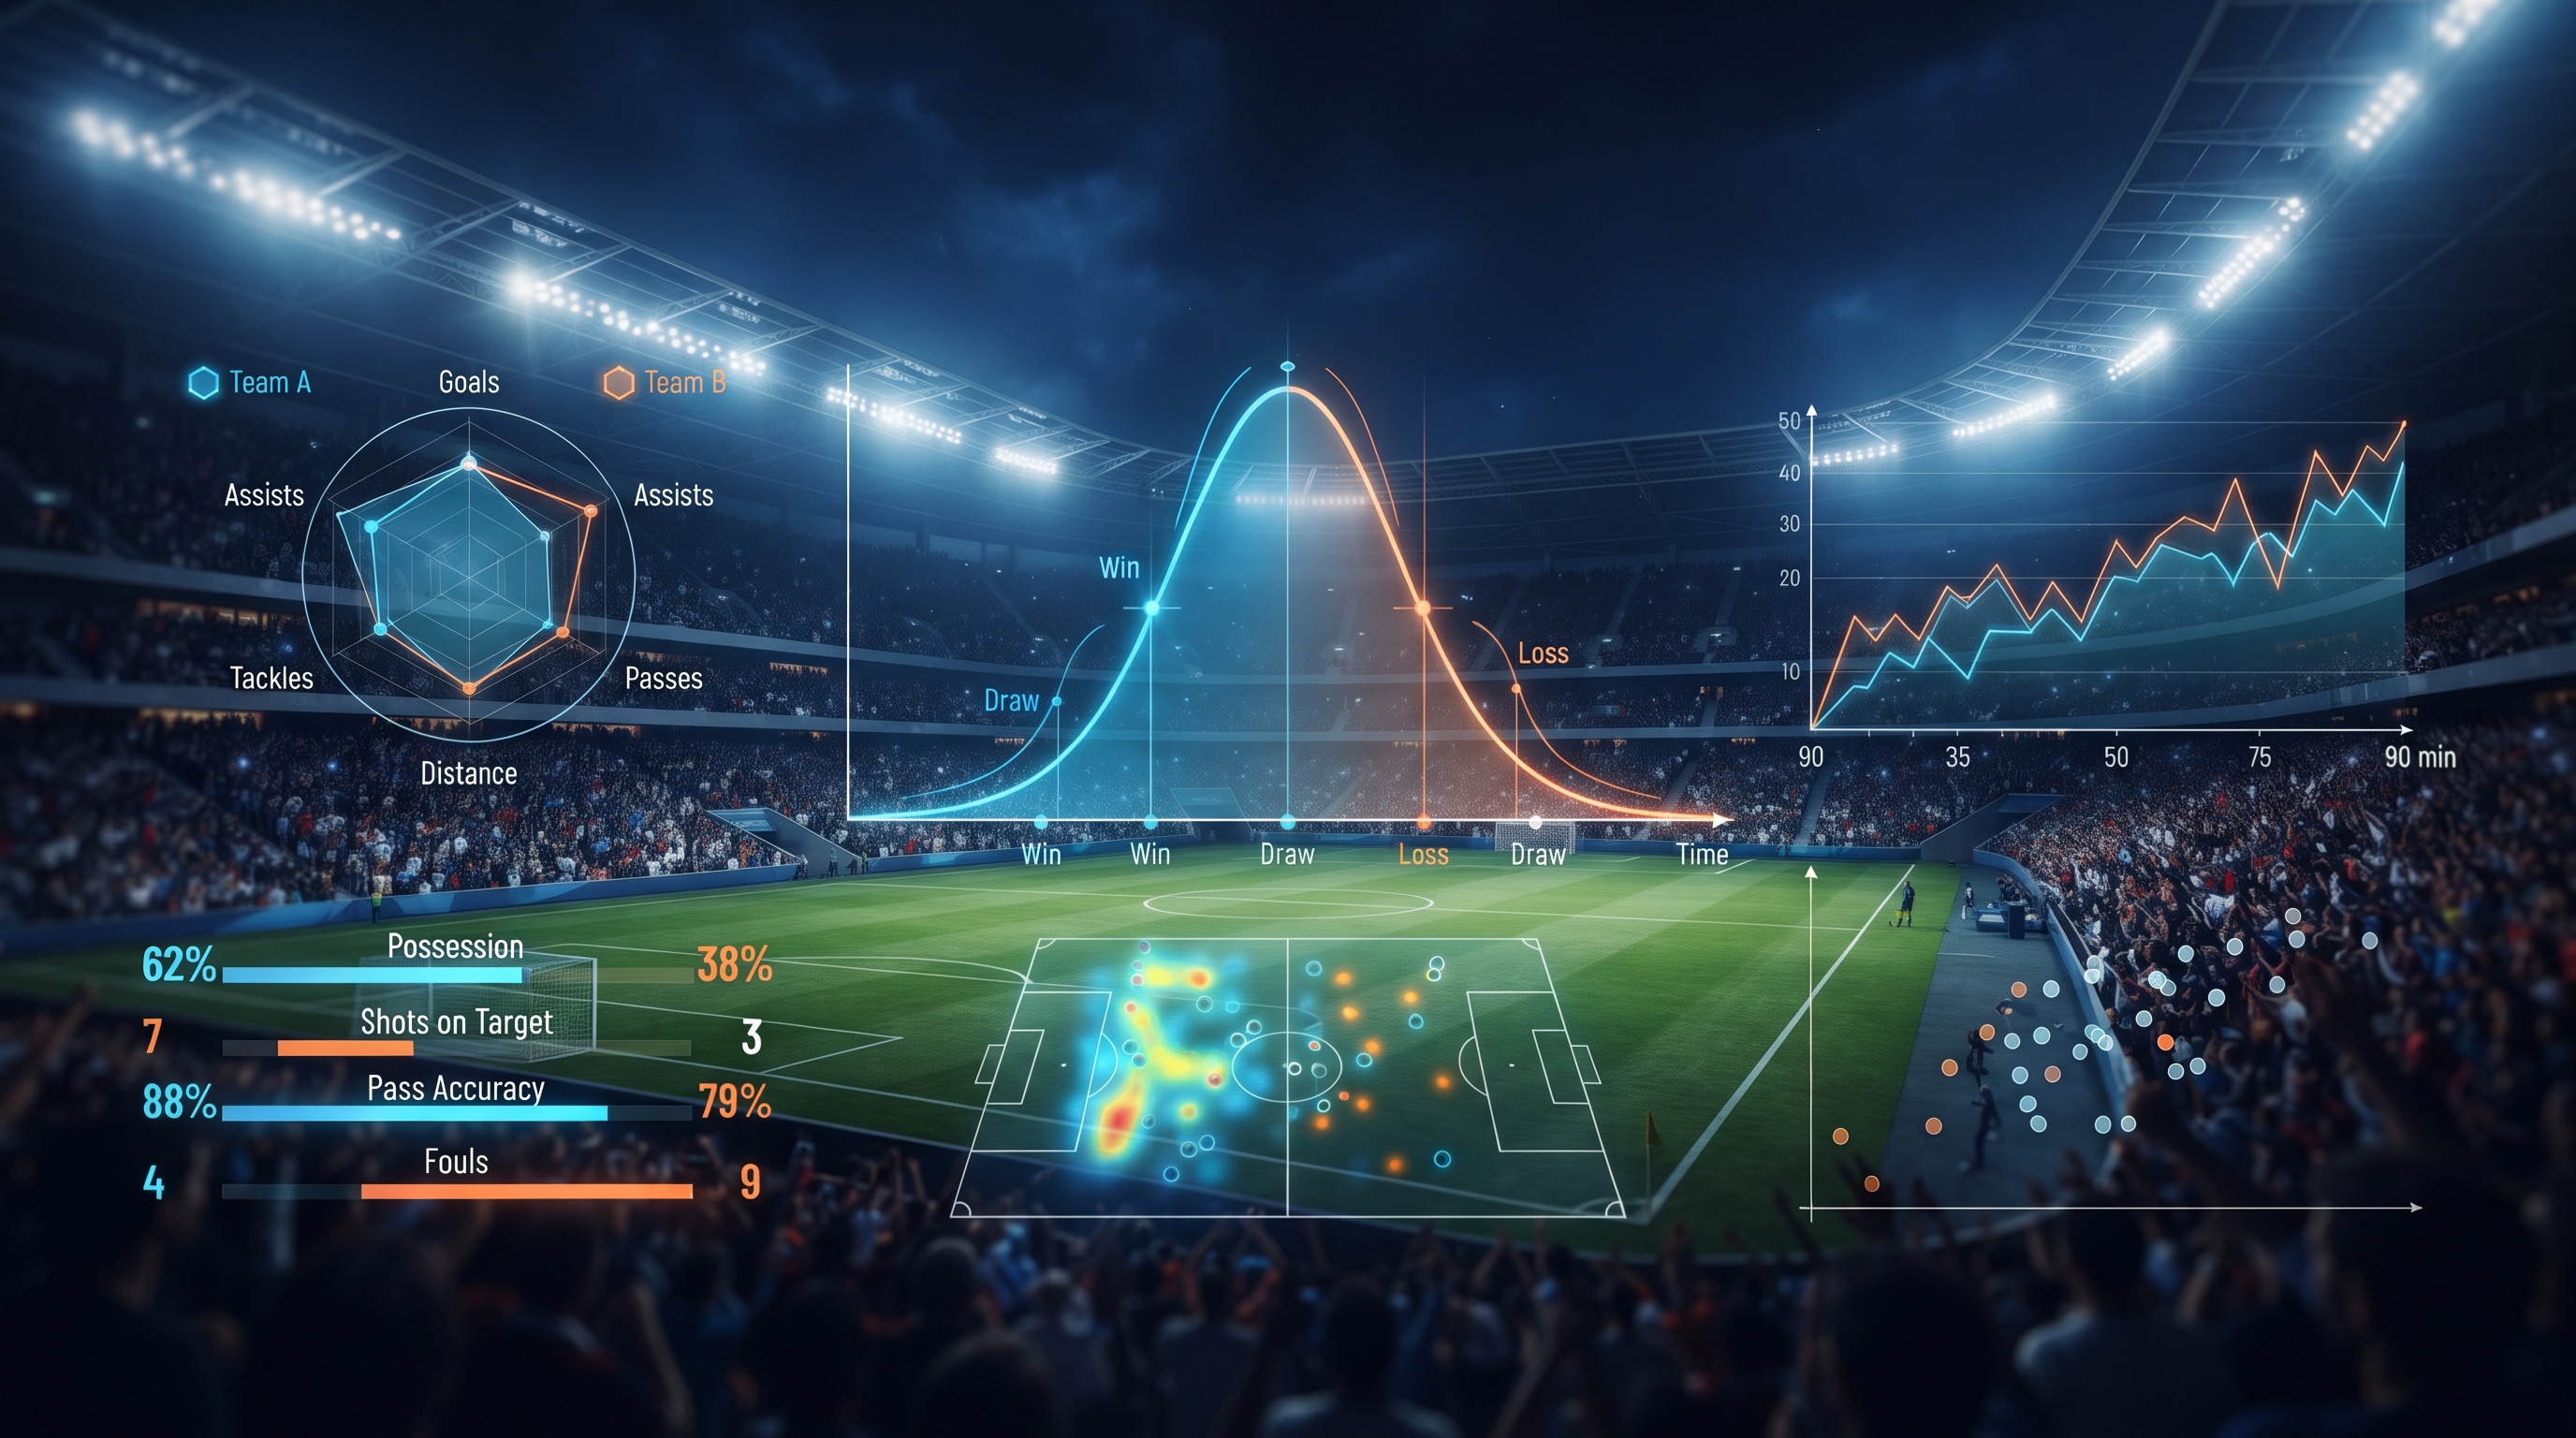
The sports analytics landscape has undergone a massive shift. Gone are the days when simple box scores, batting averages, or rudimentary win-loss records drove strategic decisions. Today, front offices, professional syndicates, and sophisticated analysts rely heavily on sports probability modeling software to simulate outcomes, price markets, and deconstruct complex game dynamics.
Whether you are looking to build proprietary models or evaluate commercial platforms like ATSWins.ai, or custom-built Python/R simulation stacks, understanding how these tools function separates casual observation from mathematical edge.
Core Pillars of Modern Sports Probability Engines
Modern modeling tools do not just look backward at what happened; they project forward to map out a distribution of potential futures.
1. Monte Carlo Simulations Over Single-Point Estimates
Traditional forecasting usually spits out a single deterministic outcome (e.g., "Team A wins by 4 points"). Advanced probability modeling software relies on Monte Carlo simulations, running thousands or millions of iterations of a single match or season.
The Mechanics: By accounting for variance in player efficiency, pace, weather, and fatigue, the engine generates a probability distribution curve.
The Result: Instead of a static prediction, analysts get a spread of likely outcomes, highlighting tail risks and true underlying win probabilities.
2. Market Efficiency Benchmarking and Closing Line Value (CLV)
In predictive modeling, beating the market closing line is the ultimate barometer of success. Top platforms incorporate historical odds tracking to measure how a model's calculated probability compares to sharp market closing prices. Consistently beating the closing line indicates that a model possesses a genuine mathematical edge rather than short-term luck.
3. Granular Data Feeds and Machine Learning Pipelines
Raw box scores miss the nuances of spatial data, tracking metrics, and contextual adjustments. Advanced software integrates multi-layered data feeds—ranging from player tracking and optical data to real-time injury reports and referee tendencies—into machine-learning classifiers that continually re-weight variables as new data flows in.
Key Use Cases Across the Industry
Probability modeling software serves several distinct niches within the sports analytics platforms with closing line value tracking ecosystem:
Professional Syndicates & Quantitative Bettors: Utilizing automated value-betting scanners and custom algorithms to find discrepancies between true calculated probabilities and sportsbook implied odds (+EV betting).
Front Offices & Coaching Staff: Simulating tactical matchups, evaluating player impact under specific tactical schemes, and optimizing in-game decision-making (e.g., fourth-down conversion choices or pitching rotations).
Fantasy Sports & DFS Optimization: Powering line-up generators that account for correlation, ceiling outcomes, and ownership projections via high-throughput simulation runs.
Building vs. Buying: Choosing Your Approach
When integrating sports probability modeling into your workflow, you generally face a choice between two paths:
| Approach | Best For | Pros | Cons |
| Commercial Platforms (e.g., Trademate, RebelBetting, OddsJam) | Analysts and bettors looking for plug-and-play workflows, real-time scanning, and automated tracking. | Instant deployment, pre-built odds integrations, out-of-the-box bankroll and variance analytics. | Limited customization of underlying core mathematical models; subscription costs scale up quickly. |
| Custom Stack (Python, R, custom SQL/API pipelines) | Quantitative researchers, developers, and advanced syndicates requiring proprietary logic. | Complete control over variables, weighting algorithms, and data sources; highly tailored output. | Requires heavy maintenance, data pipeline engineering, and statistical expertise to avoid overfitting. |
Frequently Asked Questions
1. What is the difference between sports probability modeling and standard odds-shopping?
Odds-shopping compares live lines across different sportsbooks to find the best available price for a specific wager. Probability modeling, by contrast, calculates the independent mathematical true probability of an event occurring based on data and simulations. Odds-shopping helps you secure the best price; modeling tells you whether that price actually offers positive expected value (+EV).
2. How do Monte Carlo simulations handle sudden variables like late-scratch injuries or weather changes?
Advanced models allow analysts to update input parameters dynamically in real time. When a key player is scratched or weather conditions shift (e.g., high winds in an outdoor stadium), the engine re-weights the affected variables (such as offensive efficiency or passing volume) and re-runs the simulation iterations to output an adjusted probability distribution.
3. Do I need programming experience to use sports probability software?
Not necessarily. Commercial platforms (like OddsJam or Trademate) are built with user-friendly dashboards, automated scanners, and pre-configured filters designed for non-technical users. However, building custom predictive engines, parsing proprietary optical tracking feeds, or running multi-threaded simulations requires proficiency in languages like Python or R, along with a solid background in statistics.
4. Why is Closing Line Value (CLV) considered the gold standard for model validation?
Because sports betting markets are remarkably efficient near game-time due to heavy volume from sharp syndicates, the closing line represents the most accurate reflection of true probability. If a model consistently beats the closing line (getting better odds than what the market settles at), it statistically proves that the model's edge is real and mathematically sound, rather than the result of short-term variance or luck.
Conclusion
Sports probability modeling software bridges the gap between raw data and actionable decision-making. By moving away from gut-feel analysis and toward probabilistic frameworks, analysts can accurately quantify uncertainty, evaluate expected value, and navigate variance with mathematical precision.